Case study · Document AI · 2026
 Screenshot-to-CRM pipeline
A vision-LLM pipeline that reads screenshots of workflow submissions and performance reports, drafts structured records, and publishes them to a production CRM once a person signs off.
- AI and LLM features
- Document processing
- Human-in-the-loop review
- Solo delivery
- Client
- Entertainment-industry software company
- Engagement
- Independent consulting
- Timeline
- Jul – Aug 2026
- My role
- Sole engineer
- Stack
- TypeScript · Next.js · BullMQ · Postgres
- Outcome
- Full work days cut to a few hours
On this page
We’re really happy with how V0 turned out. Everything has been handed off, and it’s been wonderful working with Ali.
Challenge
Workflow submissions and performance reports arrive as screenshots. Getting them into the client’s CRM as structured projects, roles and people records was manual work that took the team full work days. The two document types carry the same information in inverted layouts, either one project with many people or one person across many projects.
Constraints
- A wrong contact or a wrong merge is far worse than a paraphrased title, and hard to undo once it reaches production.
- Screenshots are noisy, rotated and full of small text. Generic vision-to-JSON invents fields.
- The CRM’s pages are built from frames, so a normal browser screenshot captures a blank shell.
- Model confidence isn’t a calibrated probability.
What I owned
I was the only engineer, from the first commit to production.
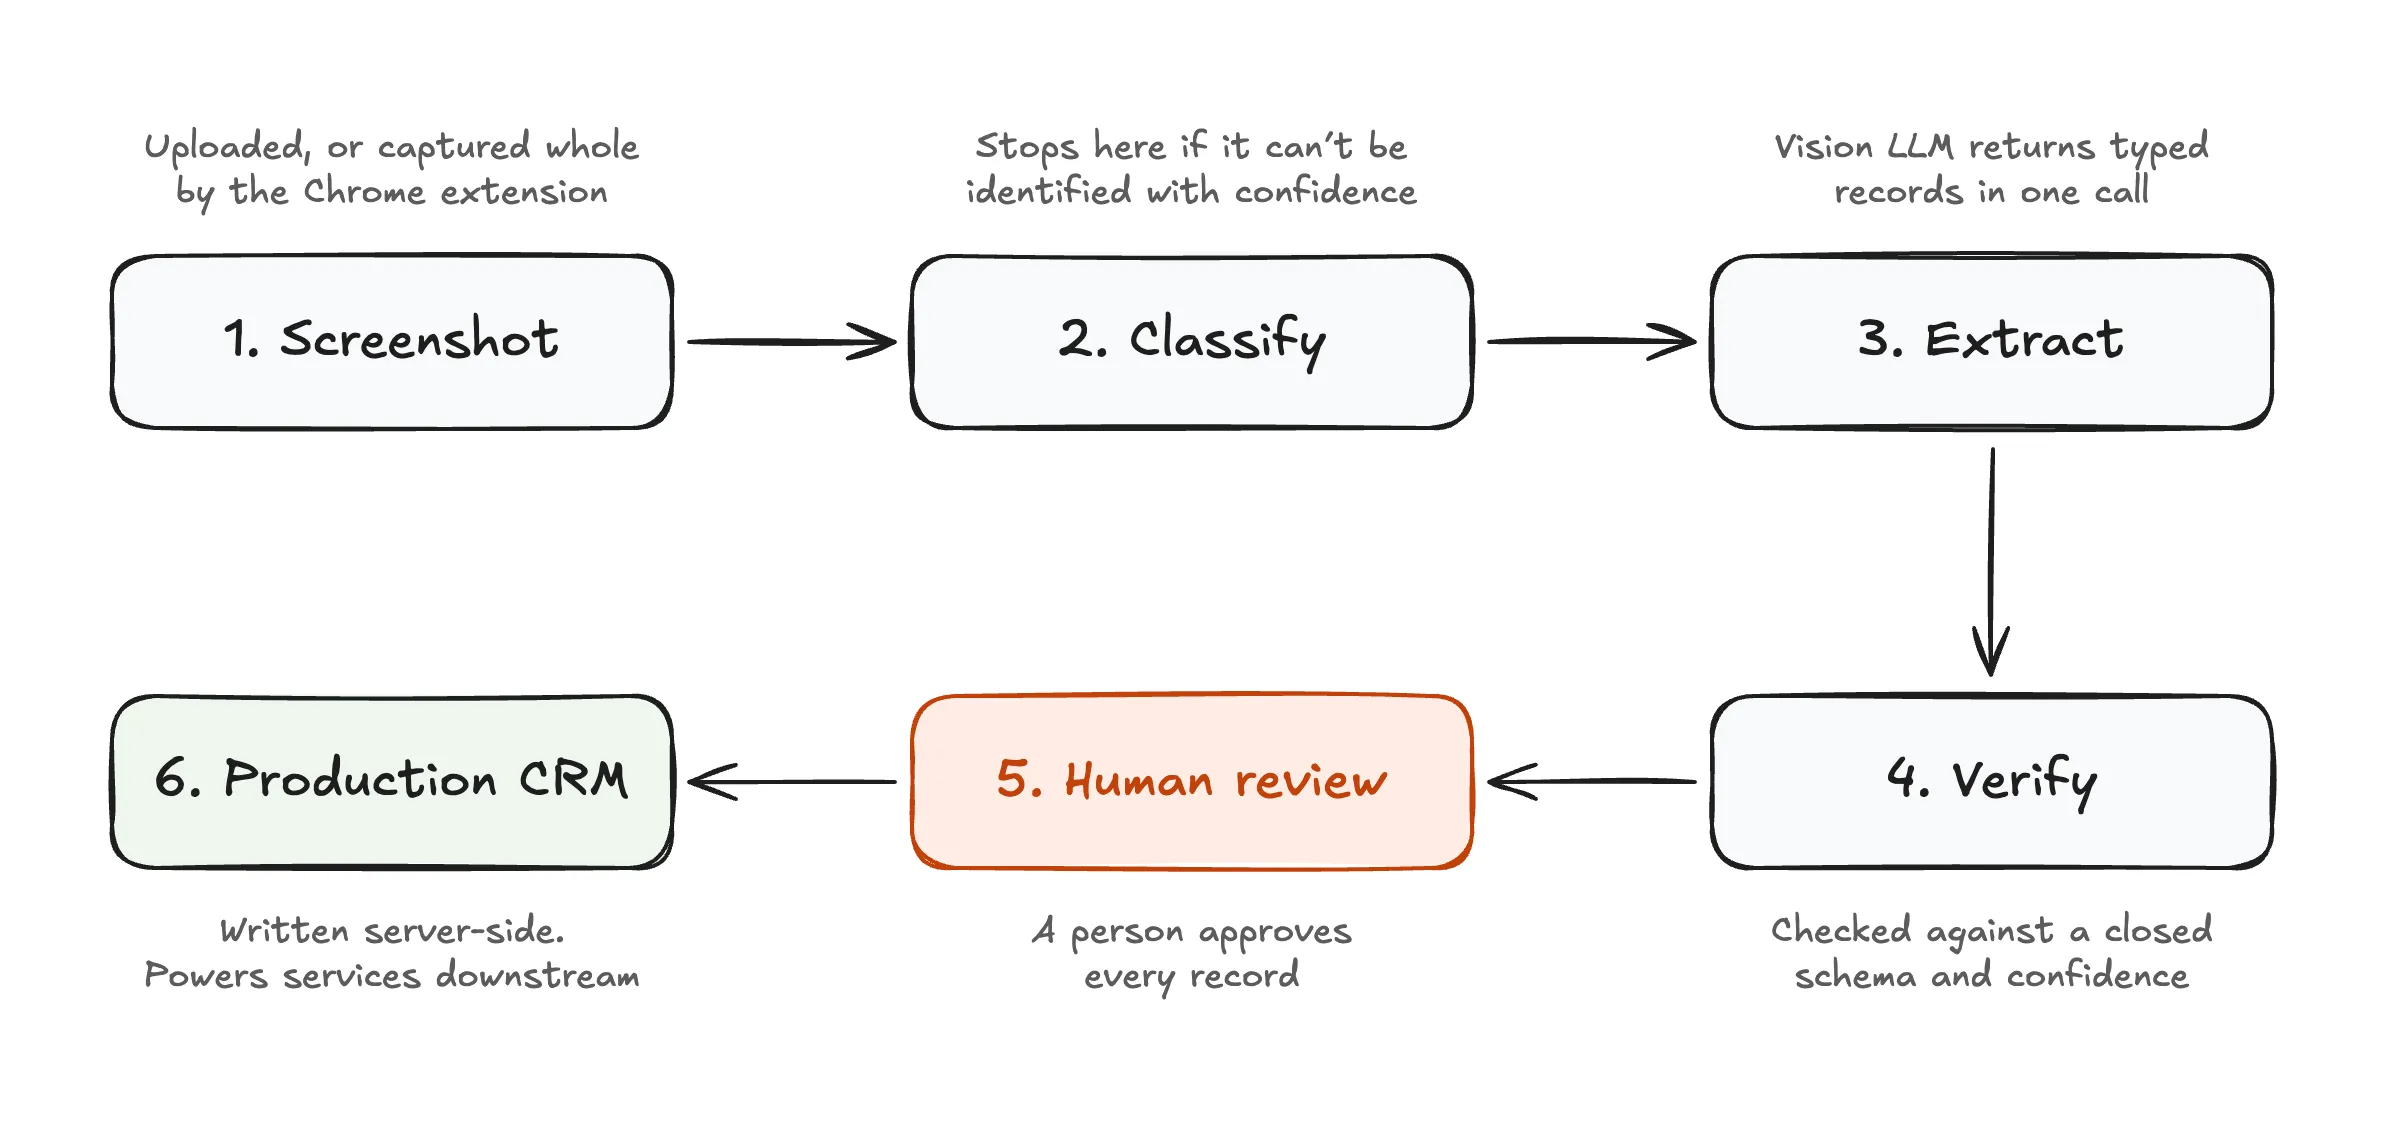
- Vision pipeline. Classify, extract, verify and enrich as queued jobs, over a closed Zod schema of entities and relationships.
- Review interface. Two review forms for the two document types, with versioned drafts and conflict detection.
- Saving to the CRM. Projects, roles and team links saved back into the client’s CRM from the server. The browser never holds the CRM token.
- Evaluation. A multi-model harness (Claude, Gemini, GPT) scoring classification and extraction against screenshots with checked, correct answers, with per-stage token and latency numbers. Every model ran through OpenRouter, so swapping one for another was a config change, not a rewrite.
- Capture extension. A Chrome MV3 side panel that captures full framed pages over the DevTools protocol and sends them for processing.
Approach
The model reads the image and emits typed records in one call, validated against a closed vocabulary. There is no separate OCR step. Classification comes first. If a document can’t be identified with confidence, it stops there, before extraction or any database write.
Trust thresholds follow the value at stake in an error. Contact details and merges need more confidence than titles, and anything uncertain goes to review instead of the CRM. A lighter model classifies and a stronger one extracts, chosen after measuring that extraction drove most of the token usage and latency.
Fuzzy cross-document merging was built, then taken out of the production flow once it proved to be the riskiest kind of mistake.
Results
- Work that took full work days of manual entry now takes a few hours.
- Getting screenshots in is now quick and orderly, and the structured records now power other services downstream.
- Structured records published to the client’s production CRM, each approved by a person first.
- Models chosen by testing them on screenshots with checked, correct answers, on accuracy, value and latency, not reputation.
- Full-page capture of the client’s framed pages, which standard browser capture couldn’t do.
Skills this shows
| If your role needs | Evidence in this project |
|---|---|
| Document AI and extraction | Schema-constrained vision extraction. A document that can’t be identified with confidence stops before extraction. |
| LLM evaluation | A multi-model harness tested on screenshots with checked, correct answers, with per-stage token and latency numbers. |
| Human-in-the-loop design | A review UI with versioned drafts; nothing reaches production unreviewed. |
| Integrating with existing systems | Saving records back into the client’s CRM from the server, with clear errors when part of a save fails. |
| Browser tooling | An MV3 extension capturing framed pages over CDP. |
What this means for your project
- Have documents or screenshots people retype? I’ll get them into your system as structured, reviewed records, and prove their accuracy and value before launch.
- Worried about AI writing bad data? I design where automation stops and a person approves, weighing the value at stake in each kind of decision.
- Need one engineer to own it end to end? This was a solo build, from browser capture to saving records back into the client’s CRM.